Research-oriented engineer · agentic AI · LLM evaluation · production ML systems

I bridge applied AI research and production-scale engineering.

Senior Software Research Engineer at Amazon with 11+ years building production ML/AI systems, large-scale distributed platforms, and research-driven intelligent systems. My work spans experiment design, prototyping novel approaches, and deploying AI systems in real-world environments.

Agentic AI LLM Evaluation RAG Measurement Temporal Reliability Cloud-Native RCA Production ML
11+ years building production ML, AI, data, and distributed systems
7+ years collaborating with research scientists, applied scientists, and economists
720K+ LLM evaluation episodes designed for robustness experiments
DSN 2026 Industry Track accepted work on decentralized RCA

Research questions I am actively working on.

My work sits in the practical middle ground between papers and platforms: rigorous enough to evaluate claims, concrete enough to run at scale, and close enough to production to expose real failure modes.

Agentic AI systems

LLM-based agents that plan, invoke tools, coordinate workflows, and operate over production data.

LLM robustness

Model behavior under delayed information, dynamic context, recovery, premature commitment, and temporal drift.

Retrieval tradeoffs

Cost-benefit analysis of RAG: when retrieval helps, hurts, wastes compute, or changes model confidence.

Cloud-native intelligence

Distributed RCA, microservice telemetry, PageRank-style diagnosis, and production observability systems.

Accepted · DSN 2026 Industry Track

Decentralized Root Cause Analysis for Cloud-Native Microservices

Experience with Distributed PageRank in production-style microservice environments.

Under review · NeurIPS 2026

LatencyBench

Evaluating LLM robustness under delayed information availability.

Under review · EMNLP 2026

The Hidden Cost of Retrieval

Quantifying when RAG helps, hurts, and wastes compute across query difficulty strata.

Under review · CIKM 2026

Temporal Hallucination in LLM Summarization

Measuring how often summaries introduce events that have not happened yet.

Peer review and program committee work.

I review work through both research and industry lenses: methodological rigor, practical relevance, reproducibility, and whether the proposed framework would survive real deployment constraints.

Reviewer · Transactions on Machine Learning Research Outstanding Reviewer · ICLR 2026 Reviewer · ACL 2026 Reviewer · RecSys 2026 Reviewer · Amazon Machine Learning Conference 2026 Technical Program Committee · DSN CRAI Workshop 2026
Amazon · Seattle

Senior Software Research Engineer

Building production agentic AI systems, orchestration frameworks for tool-augmented LLMs, ML infrastructure, Kubernetes platforms, and large-scale data systems.

Senior Software Development Engineer

Jul 2022 - Present
  • Created LLM-based agents using AWS Agent Core to resolve book/author data mismatches and calculate US sales on Amazon.com.
  • Developed Kubernetes applications with GPU scheduling and custom operators, improving scalability by 45%.
  • Built an EKS/Flux service for deploying YAML configs and provisioning VSCode containers for ad hoc Spark analysis.
  • Designed reusable CDK constructs for deploying machine-learning infrastructure across AWS accounts.

Data Engineer II

Sep 2019 - Jun 2022
  • Built the Speed Impact Pipeline to process training data and run econometric models on EMR.
  • Parallelized winsorization of two-dimensional matrices using multithreading.
  • Migrated AFN-FCP SQL workloads from Redshift to Spark, improving runtime by 30% and reducing IMR by 60%.

Software Engineer

Comscore · 2017 - 2019
  • Architected Snapchat data integration into Comscore datasets under data governance constraints.
  • Built reusable Scala libraries for Spark jobs and custom input formats for 10K partition datasets.
  • Placed second globally in a Comscore hackathon with a Spark monitoring tool using Graphite and Grafana.
01 LLM evaluation

LatencyBench

A two-phase benchmark for measuring how delayed information changes LLM behavior: premature commitment, waiting, recovery, and decision stability.

  • Designed experiments across frontier models, public datasets, and delay levels.
  • Defined behavioral metrics including PCR, wait rate, recovery gain, and stability.
  • Built worker, prompt, dataset, scoring, and deployment scaffolding.
Repository
02 Retrieval systems

Retrieval Value Maps

A measurement framework for identifying when RAG retrieval helps, hurts, or wastes compute on public-knowledge question answering tasks.

  • Implemented BM25, dense retrieval, RRF, reranking, and oracle retrieval paths.
  • Prepared large-scale Wikipedia passage corpora and gold evidence extraction.
  • Analyzed no-op retrieval, judge sensitivity, hedging, and failure taxonomy.
Repository
03 Cloud-native AIOps

Swarm RCA for Microservices

A decentralized and centralized root-cause analysis system for cloud-native microservices using anomaly detection, service graphs, gossip, and Personalized PageRank.

  • Built Kubernetes sidecar agents that exchange rank vectors over gRPC.
  • Used AWS CloudWatch Container Insights and X-Ray telemetry for service graph signals.
  • Created a centralized baseline to compare distributed and centralized RCA behavior.
Repository

Tools I use to build research-grade AI systems.

I combine systems engineering depth with research workflows: experiment pipelines, model evaluation, agent orchestration, retrieval infrastructure, and production deployment.

Languages

Java/J2EEScalaPythonC#SQL

AWS & Cloud

EKSEMRAgent CoreEC2GlueS3RedshiftVPCRDSCDK

Big Data

SparkPySparkHadoopMapReducePigGreenplum

Platforms & Web

KubernetesFluxSpring MVCHibernateASP.NET MVC5REST APIsGrafana

Experimental evidence, not just project descriptions.

Selected plots from evaluation and retrieval work, included to make the profile closer to a research record than a conventional resume.
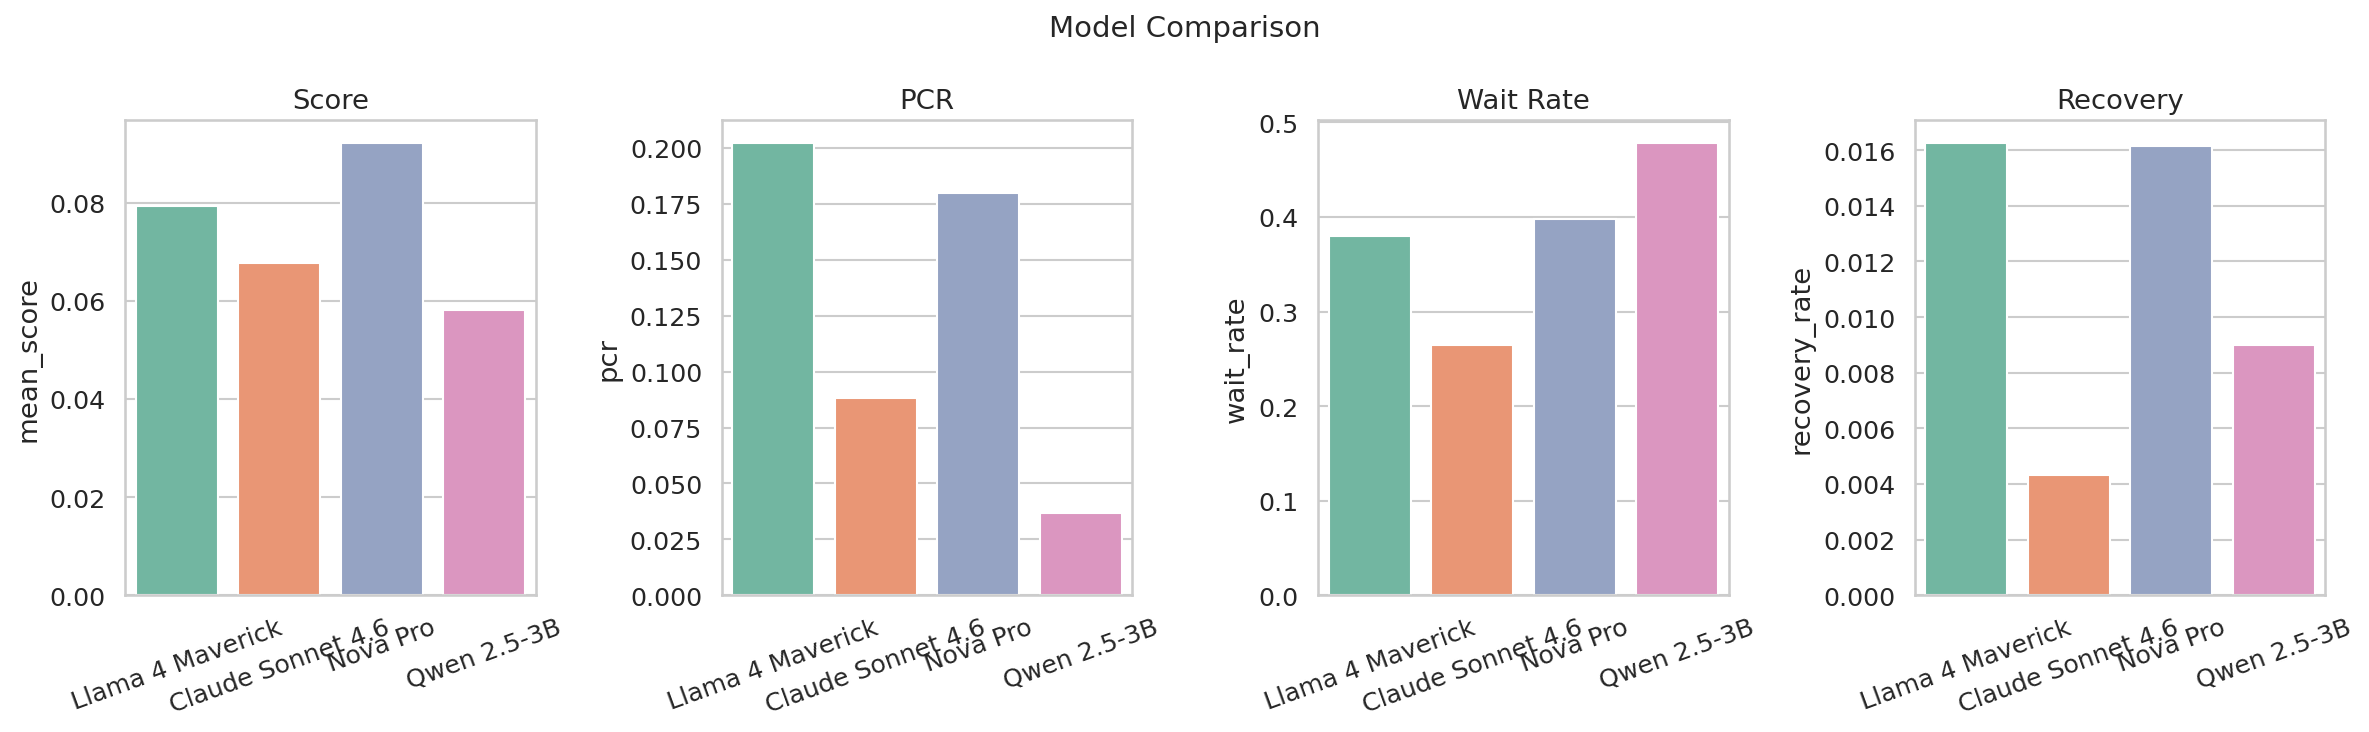
Model comparison plot from LatencyBench
Model comparison across benchmark conditions.
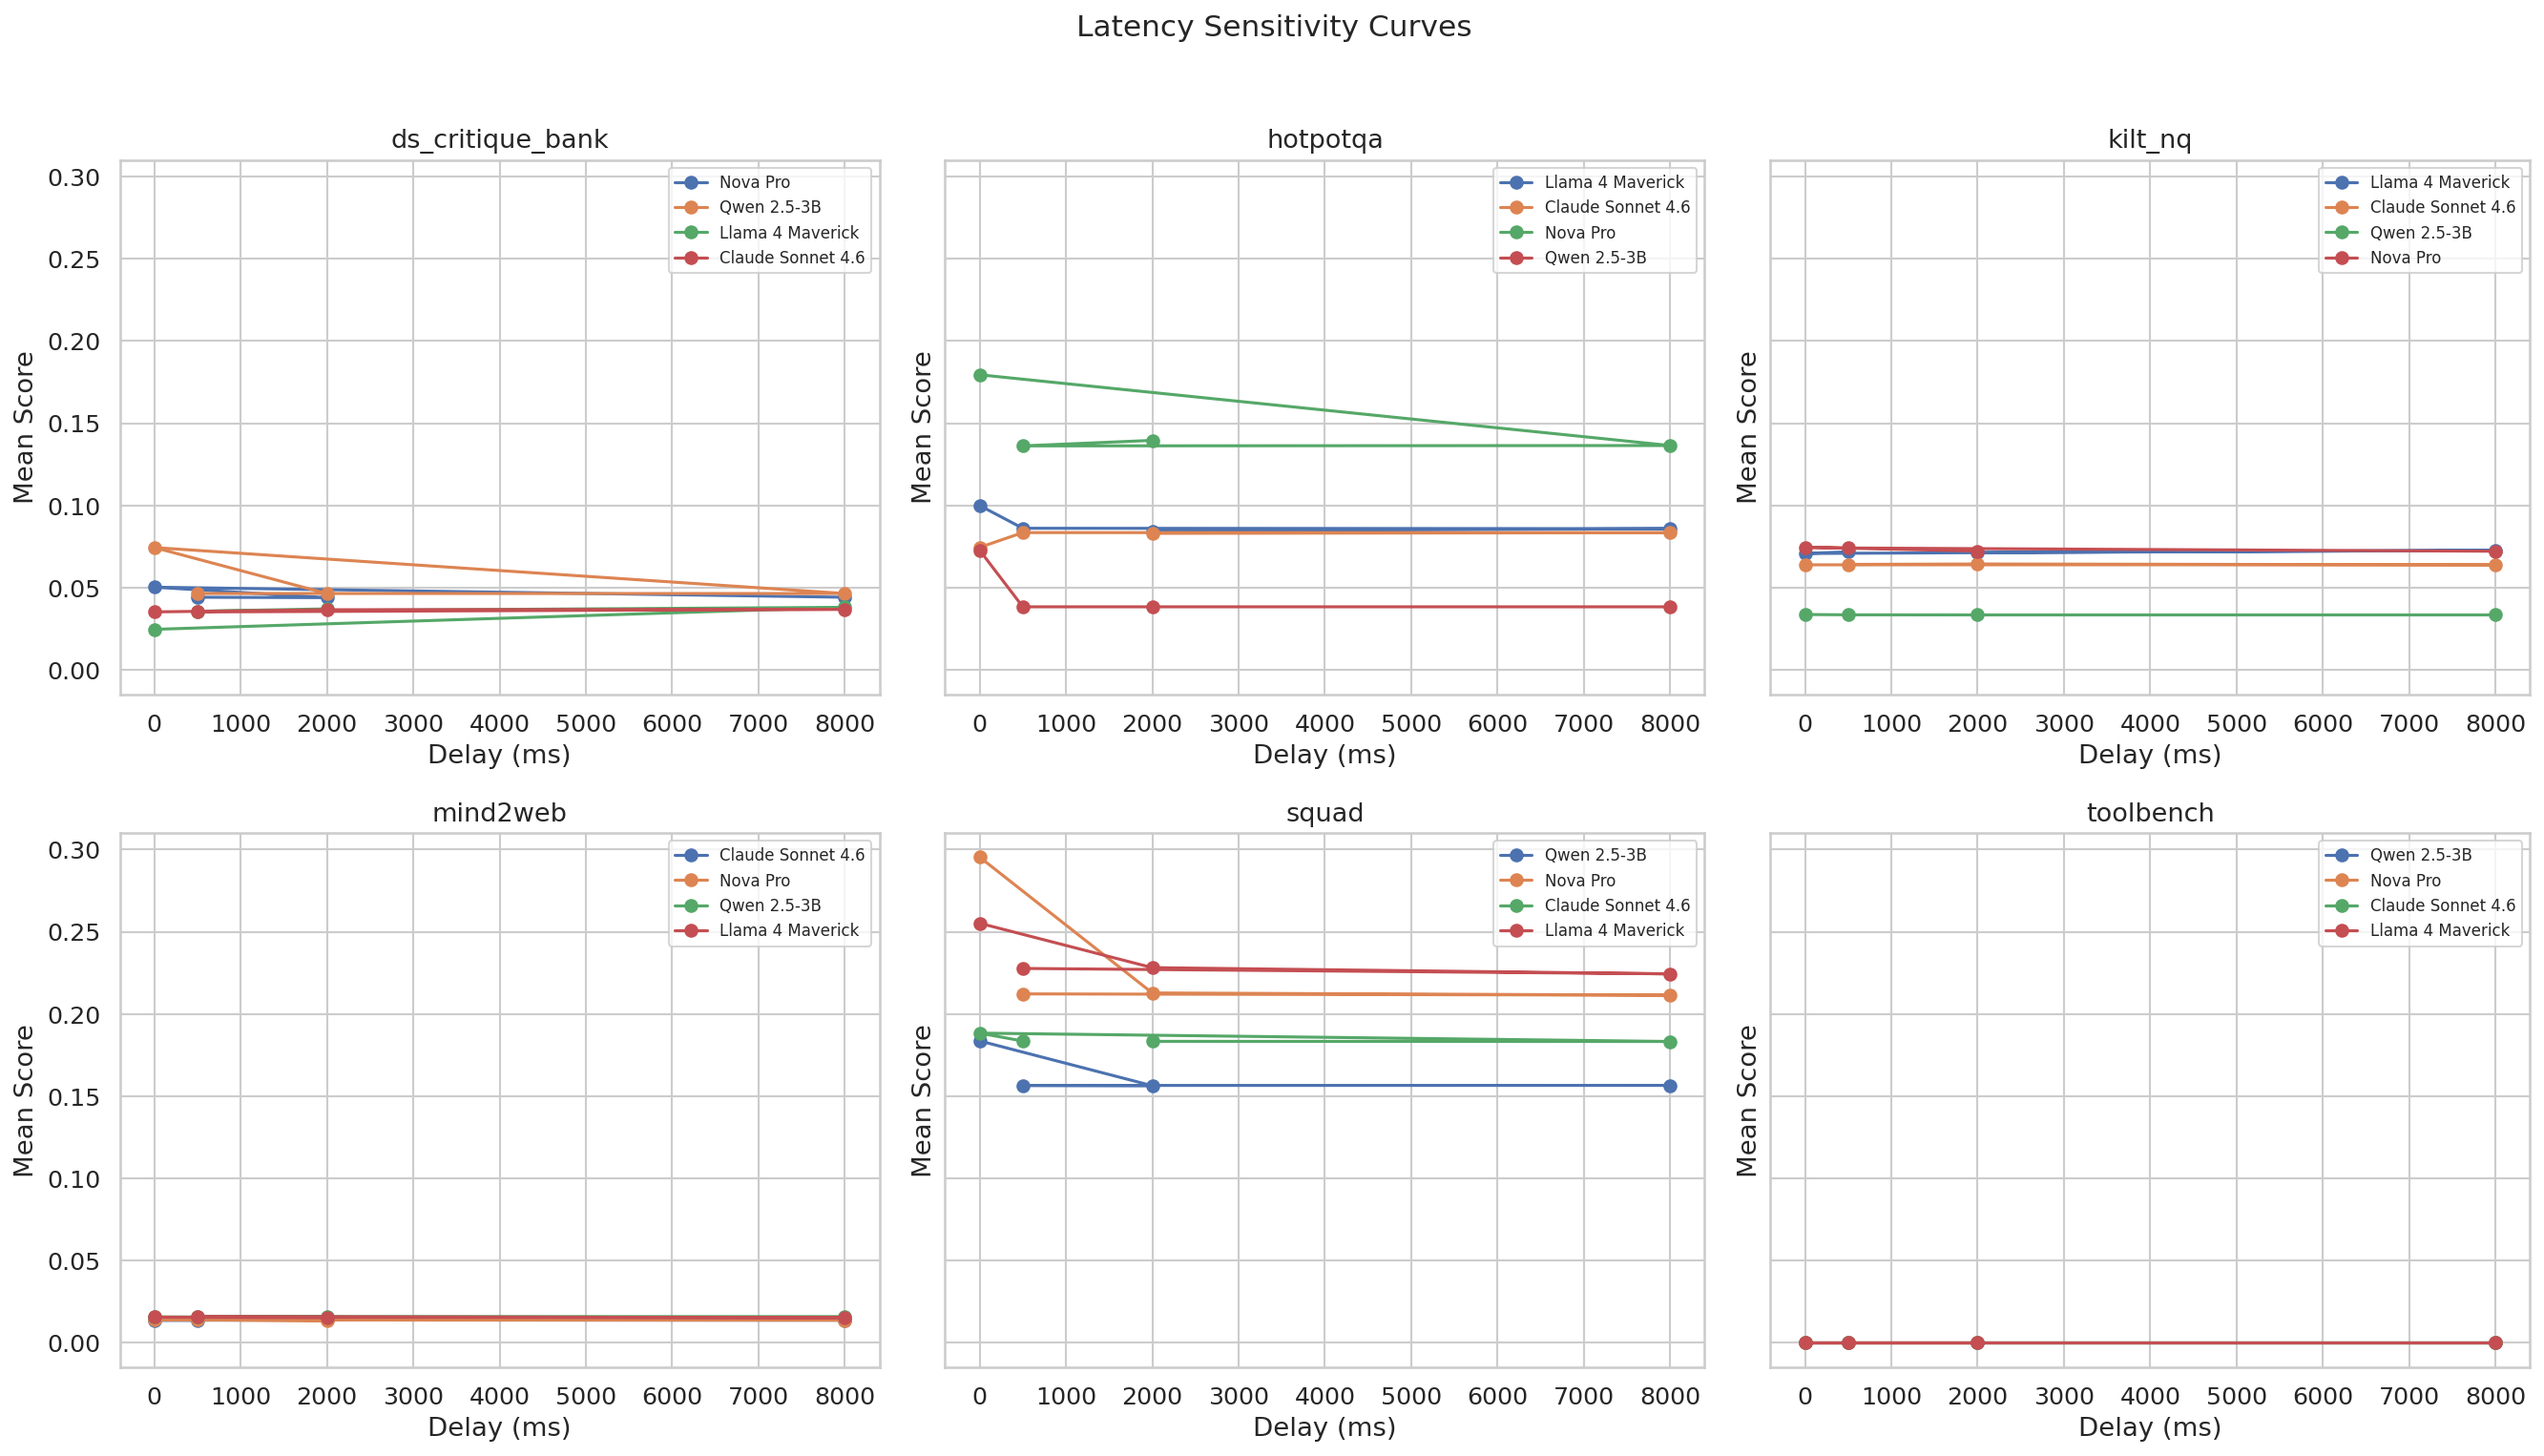
Latency sensitivity curves plot
Delay sensitivity curves across information timing.
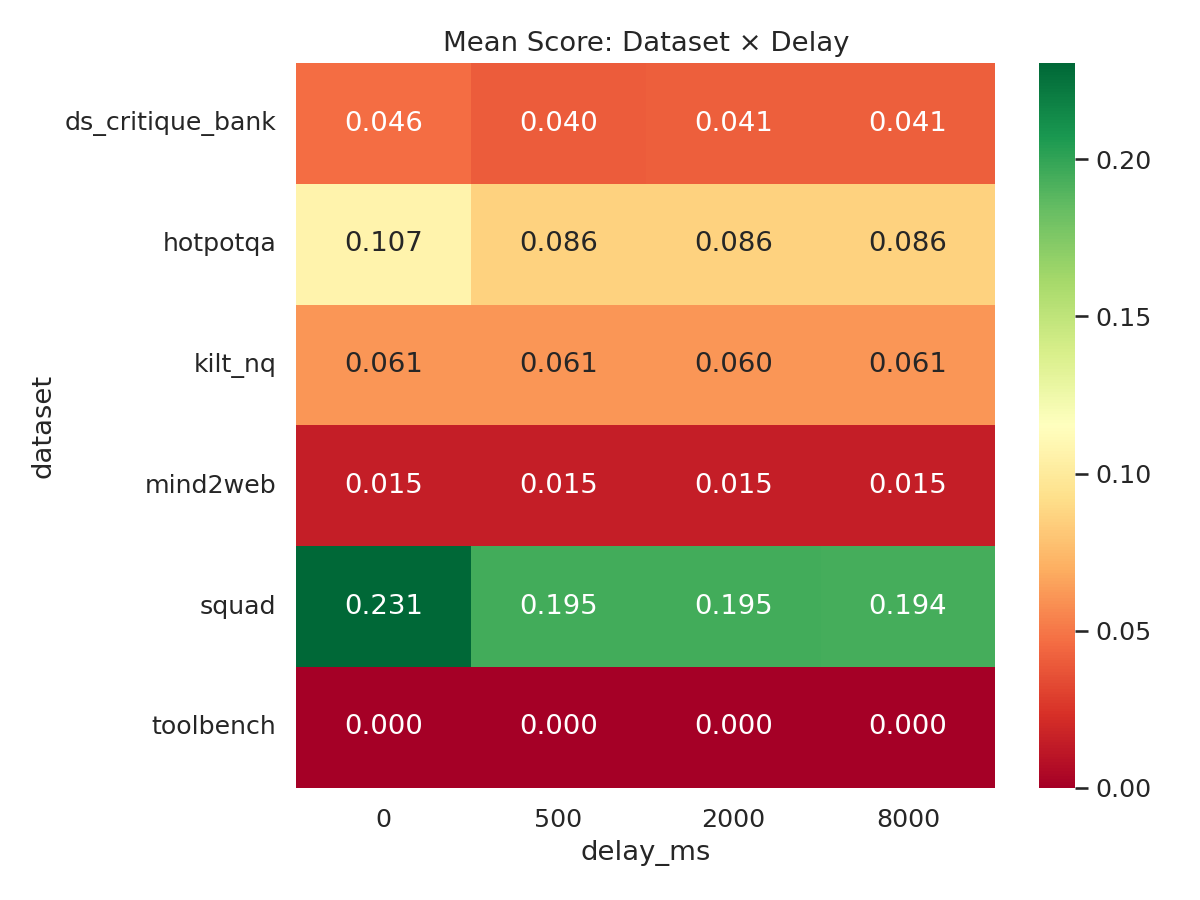
Dataset by delay heatmap
Dataset-level interaction patterns by delay.
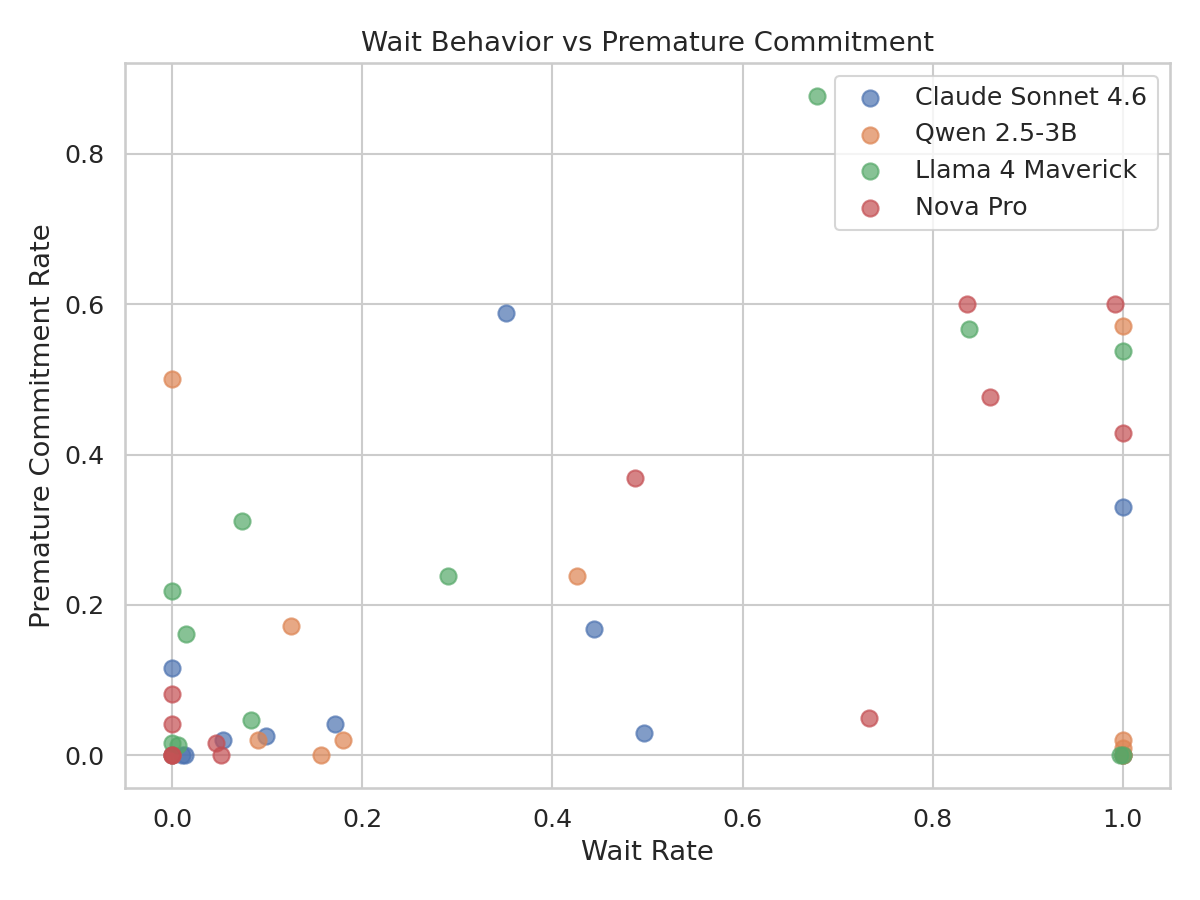
Wait rate versus premature commitment plot
Wait behavior compared with premature commitment.

What makes my profile research-oriented.

Applied research translation

I translate research questions into experiment designs, prototypes, evaluation pipelines, and systems that can be tested under production constraints.

Scientific collaboration

I have worked closely with research scientists, applied scientists, and economists on research direction, data generation, model deployment, and evaluation workflows.

Communication

I care about writing that makes systems understandable: clear methodology, practical tradeoffs, and enough detail for another engineer to reproduce the work.

Inspired by strong GitHub profile patterns.

I used the awesome GitHub profile README collection as a styling reference, but adapted it for a homepage: visible badges, resume access, skills, experience, project depth, and restrained polish instead of a wall of widgets.

For research teams and engineering groups building serious AI systems.

I am interested in rigorous work across agentic AI, LLM robustness, retrieval, temporal reliability, AIOps, Kubernetes platforms, and infrastructure for reliable AI.